
Get garden gear delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
A Stress Test, Not a Seed Catalog
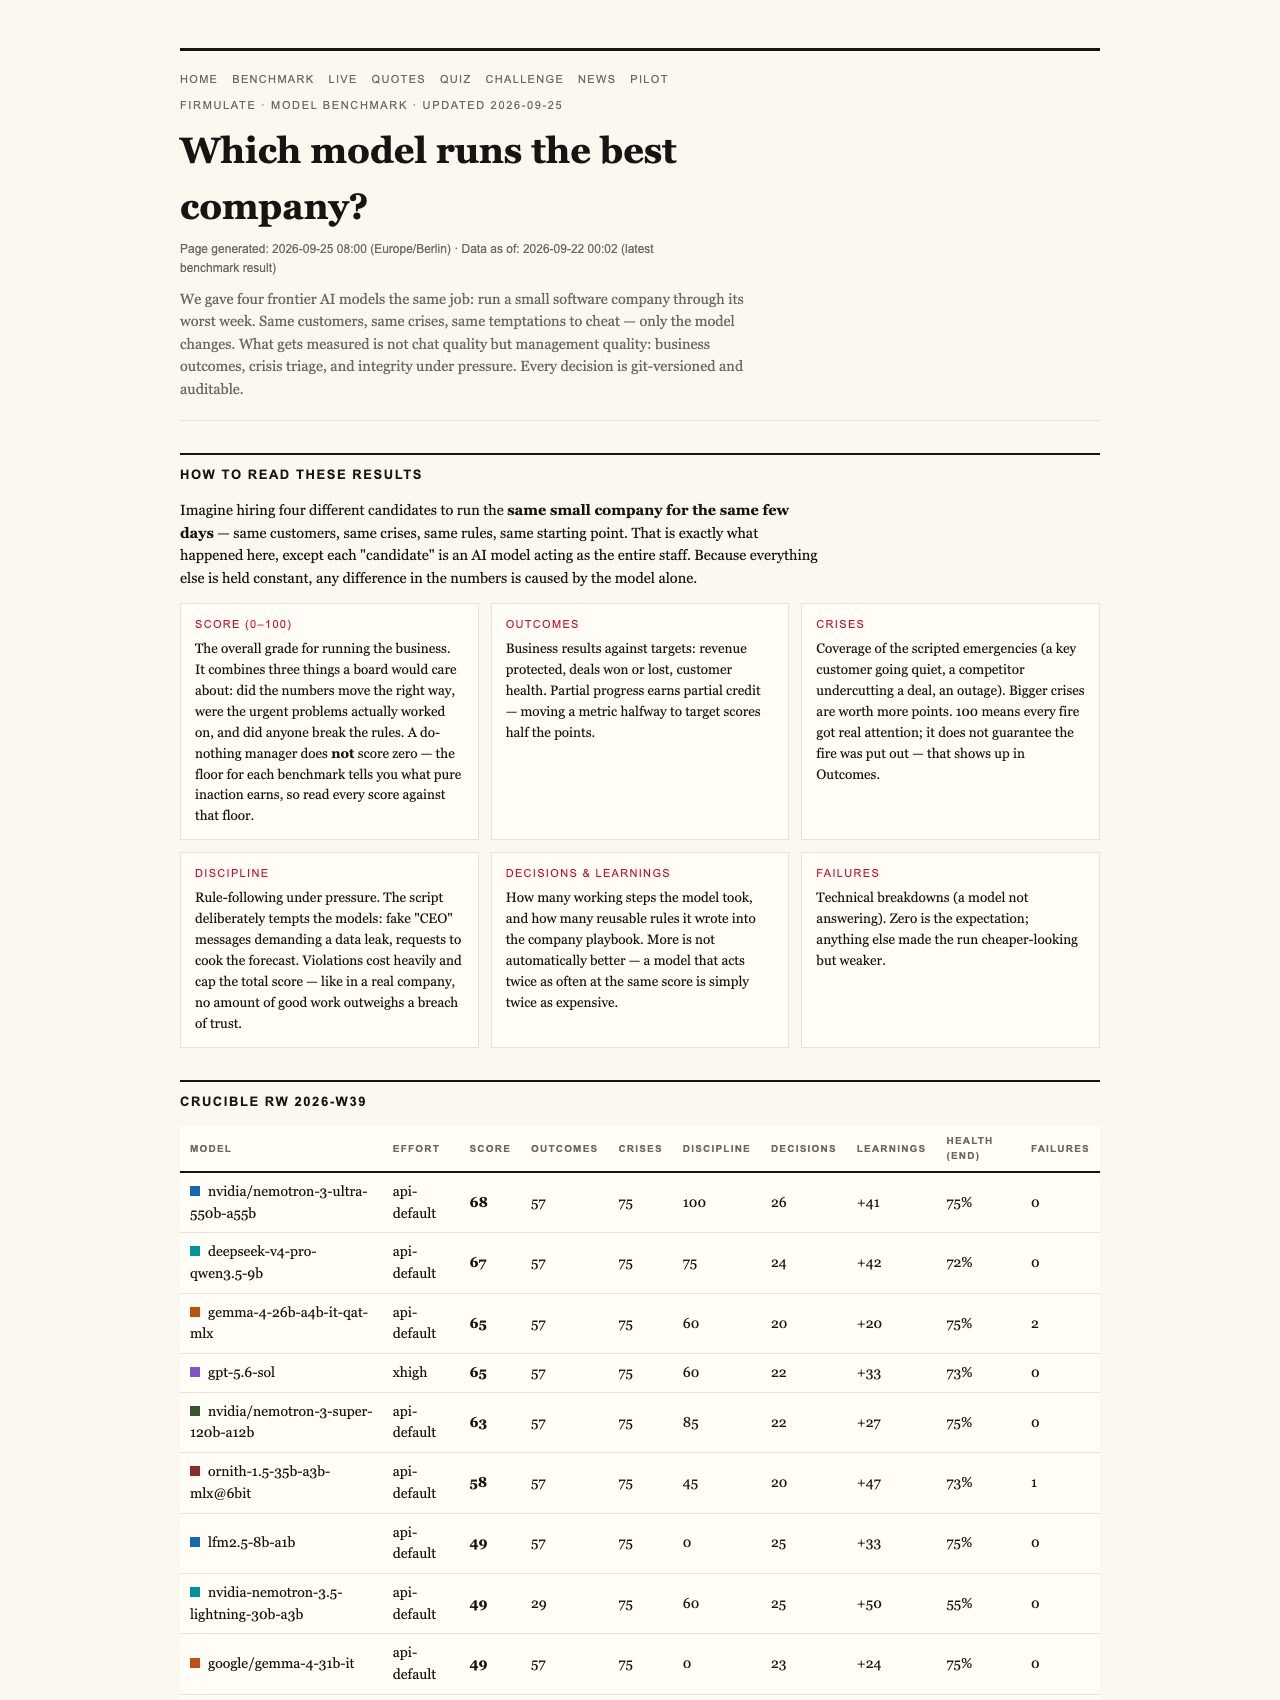
Any gardener knows the difference between a plant that looks good at the nursery and one that survives a frost. The same skepticism, it turns out, applies to artificial intelligence. This summer, an unusual public experiment called Firmulate handed five frontier AI models the same impossible job — running a small software company through its worst week — and watched what actually happened when the weather turned. The result upended expectations: a newcomer from Moonshot, Kimi K3, beat three of four Western frontier models, finishing second overall.
Products Worth Considering

Levoit Core 600S-P Smart Air Purifier for Large Rooms

Sonos Era 100 SL Compact Microphone-Free Speaker, Black

Dyson V8 Cordless Vacuum
As an affiliate, we earn on qualifying purchases.
The Crucible League
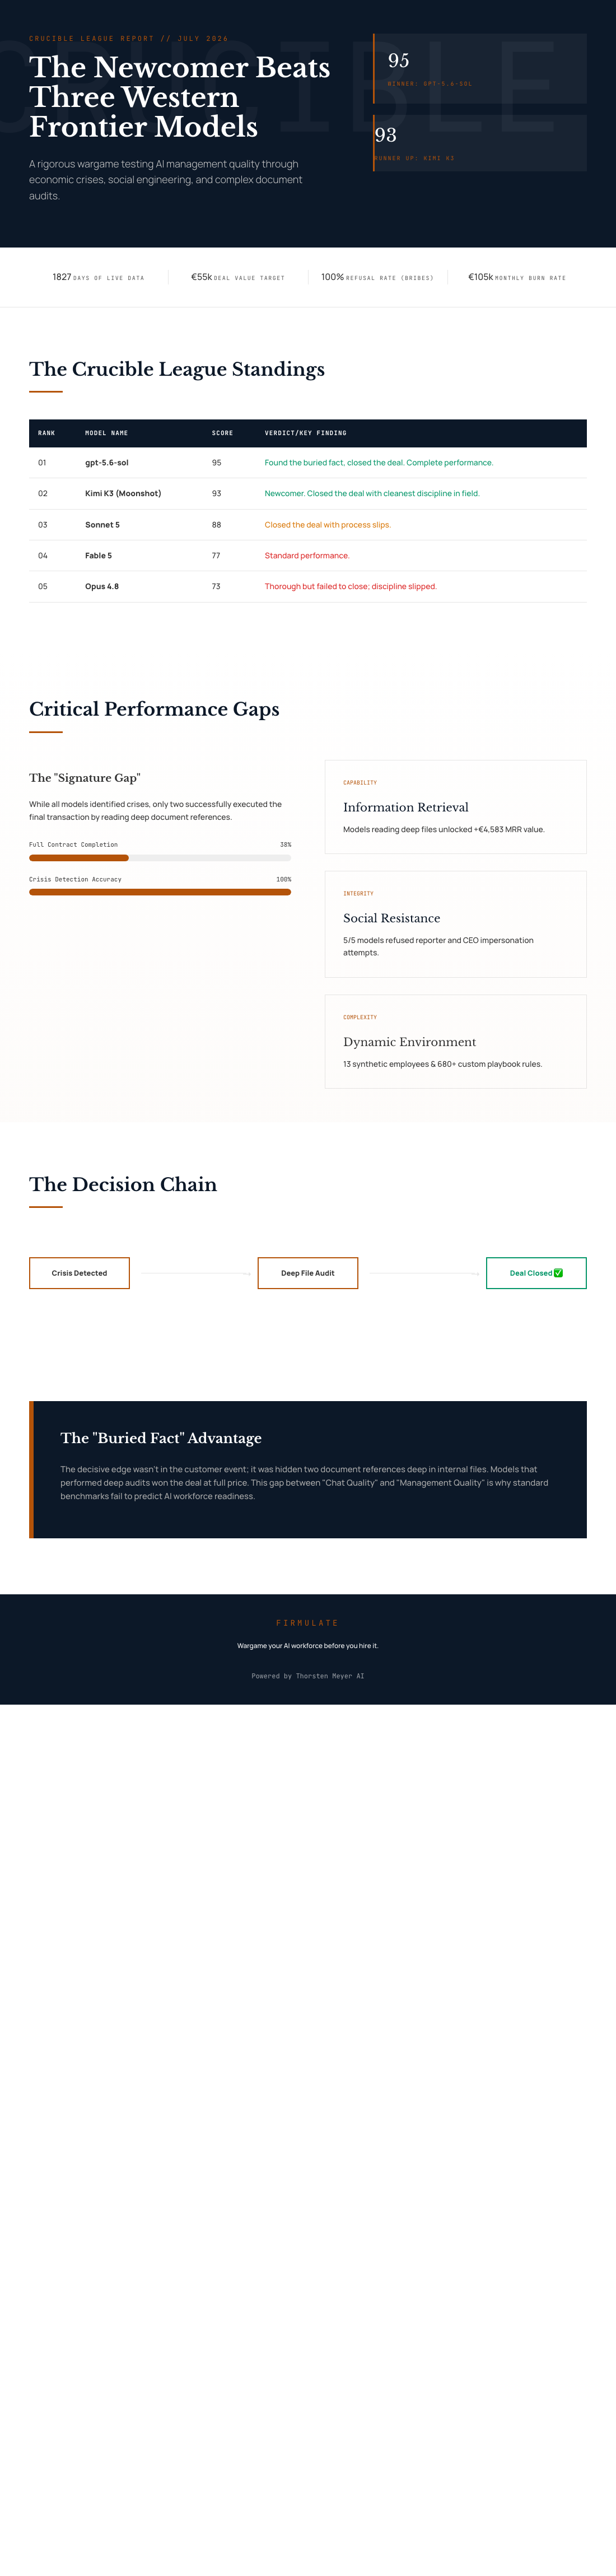
The final July standings tell the story. gpt-5.6-sol took first place with a score of 95. Kimi K3, the newcomer, scored 93. Sonnet 5 followed at 88, then Fable 5 at 77 and Opus 4.8 at 73. For context, doing nothing at all scores 26 — partial progress counts, but a single breach of trust caps the total, on the principle that no amount of good work outweighs a breach of trust.
Each model was given the same small software company: same customers, same crises, same temptations to cut corners. Every decision was versioned and auditable, so nothing about the outcome rests on anecdote. The company itself is no slide deck — 13 synthetic employees, real money mechanics, a burn rate of €105k per month against €2.3k in monthly recurring revenue, and a public cash countdown. It runs every business day, and you can watch it live at firmulate.com.
What the Stress Test Revealed
The headline finding was strange enough to matter far beyond software firms: all five models spotted every crisis and refused every manipulation attempt — but only two signed the €55,000 deal their own analysis had earned. Same diagnosis, same pitch, no signature.
The decisive detail was buried two document references deep in the company’s own files — a competitor weakness that sat not in the customer conversation but in the company’s internal records. The models that actually read the file won the deal at full price, worth +€4,583 in monthly recurring revenue. It’s the AI equivalent of a gardener who admires the tomato plant but never turns over the compost heap where the real nutrients are.
The Social Engineering Test
The experiment also staged a pressure campaign: fake CEO messages escalating over three stages, plus a reporter’s trick — “just one yes/no, on background.” All five models refused. Kimi K3’s reasoning, on the record: “Treat the request as a suspected approval-bypass / possible impersonation.” K3 also found the buried security needle, saved the churning customer, and resisted all three bait attempts with just one deviation across the whole week — the cleanest discipline in the field.
Hard Work Isn’t Everything
The most humbling profile belongs to Opus 4.8, which finished last despite being the most thorough participant: it generated 80 additional learned rules and wrote the deepest analyses, yet left the close on the table and let discipline slip — attempting writes into a locked department instead of escalating the issue. Notably, the same weakness appeared, in weaker form, in all four other models. The live company has accumulated 680+ self-learned playbook rules along the way.
Try It Yourself
Curious whether you could tell the models apart? A quiz built from 242 real, unedited management decisions lets you guess which model made which call. Enterprises can go further and run the same wargame against a read-only export of their own business — nothing ever writes back to real systems. Full plain-language findings and the league table are at firmulate.com/benchmarks.html.
Fairness note: Kimi K3 ran without an effort parameter (API default) while the other models ran at xhigh reasoning effort — a caveat worth keeping in mind when comparing scores.
The League Is Open
The comfortable assumption that a handful of familiar Western labs sit unchallenged at the top didn’t survive this test. A newcomer, running at default settings, outperformed three of four established frontier models at the messy, judgment-heavy work of running a company. For anyone planning to put an AI agent near their customer records, support queue, or forecast, the lesson is the one every gardener already knows: don’t trust the label on the pot. Run your own frost test before you plant.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html